Live
Practice 01 of 04
What we deliver
Retrieval-augmented systems with hybrid search, reranking, and evaluation — grounded answers over your own data.
Multi-step agents that plan, use tools, and act safely, with human-in-the-loop where it matters.
Task-specialized open models (LoRA/QLoRA) with reproducible evaluation against real baselines.
Quantization and ONNX conversion for privacy-preserving, offline-first inference on constrained devices.
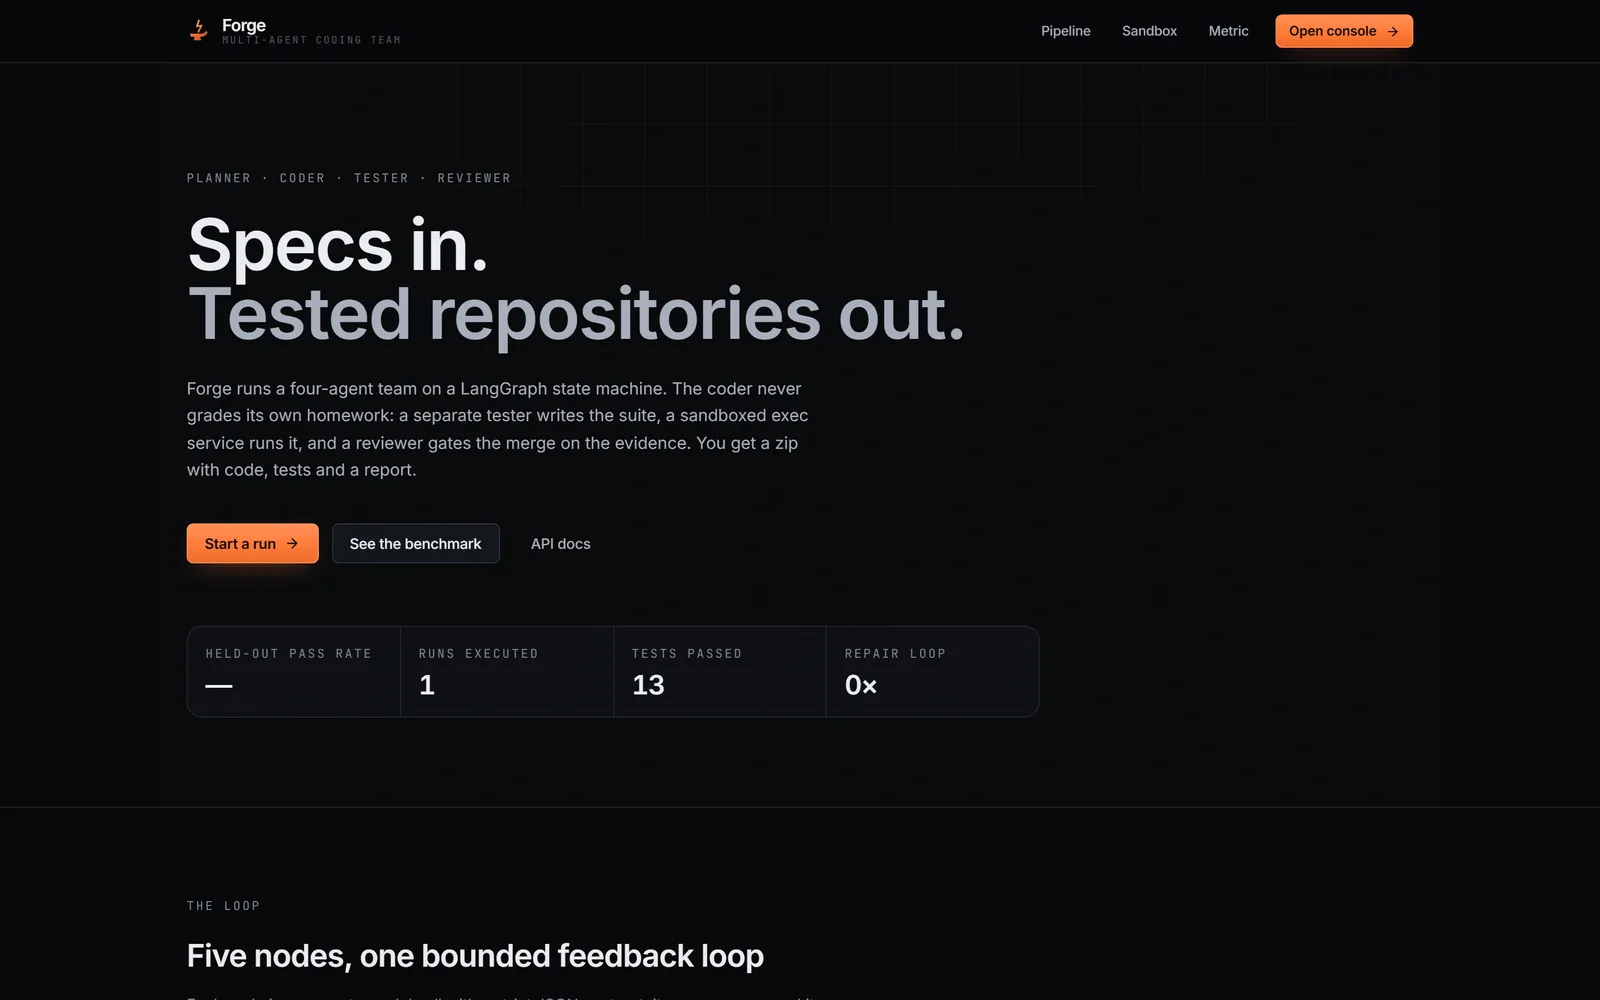
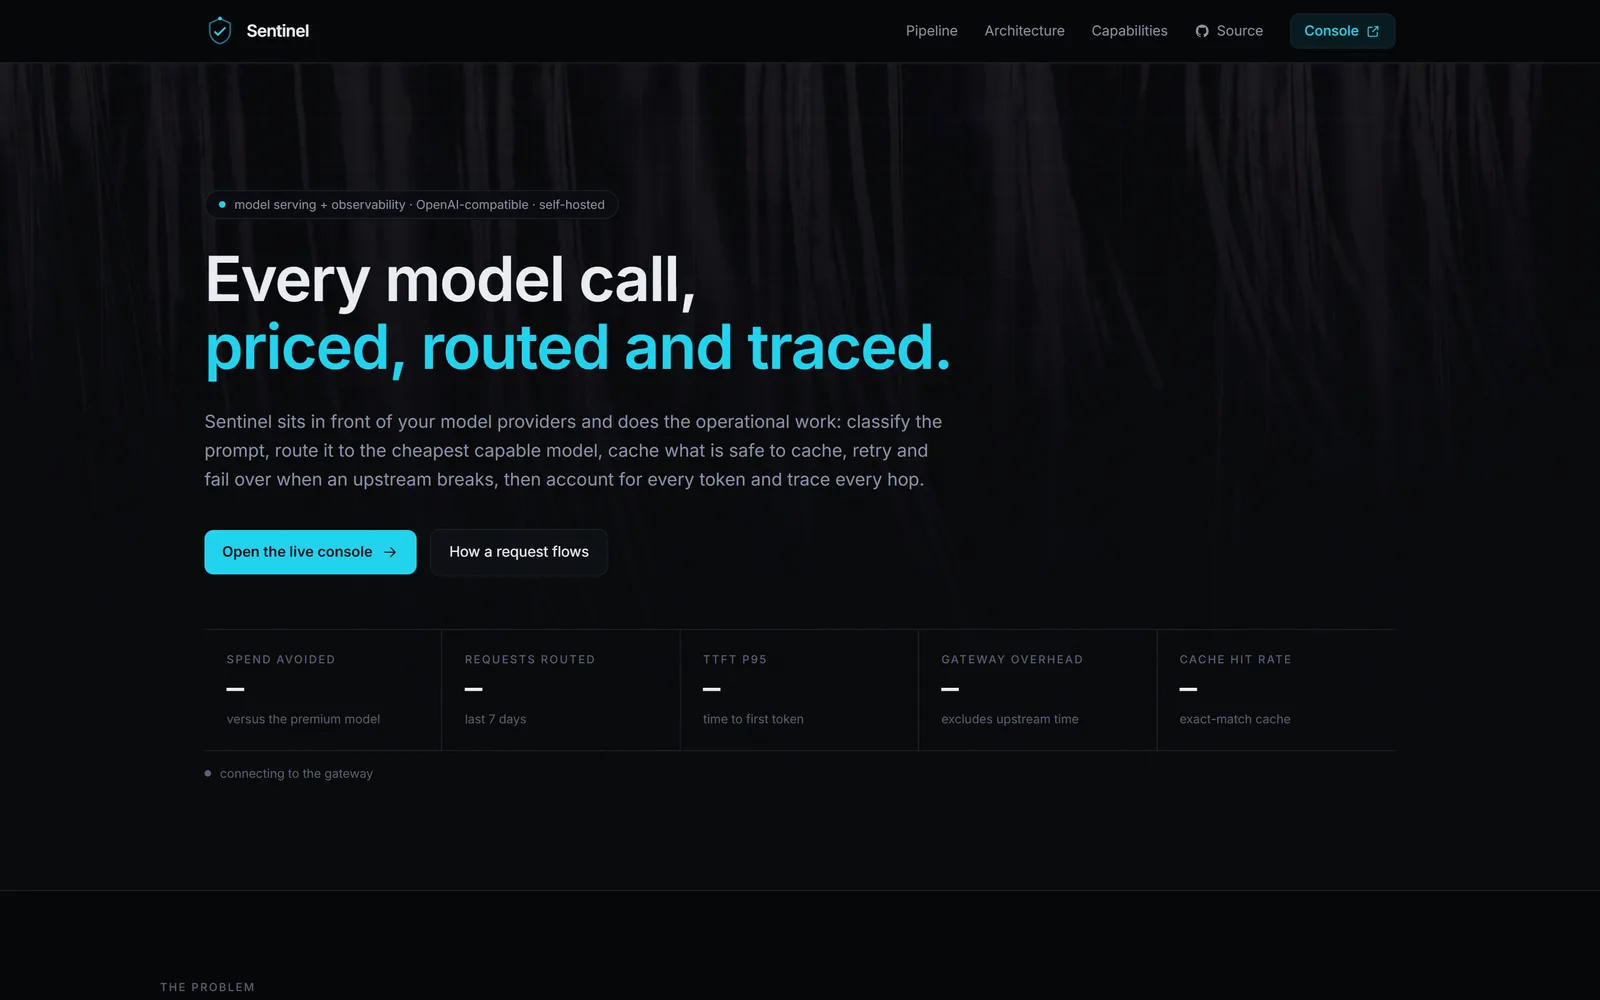
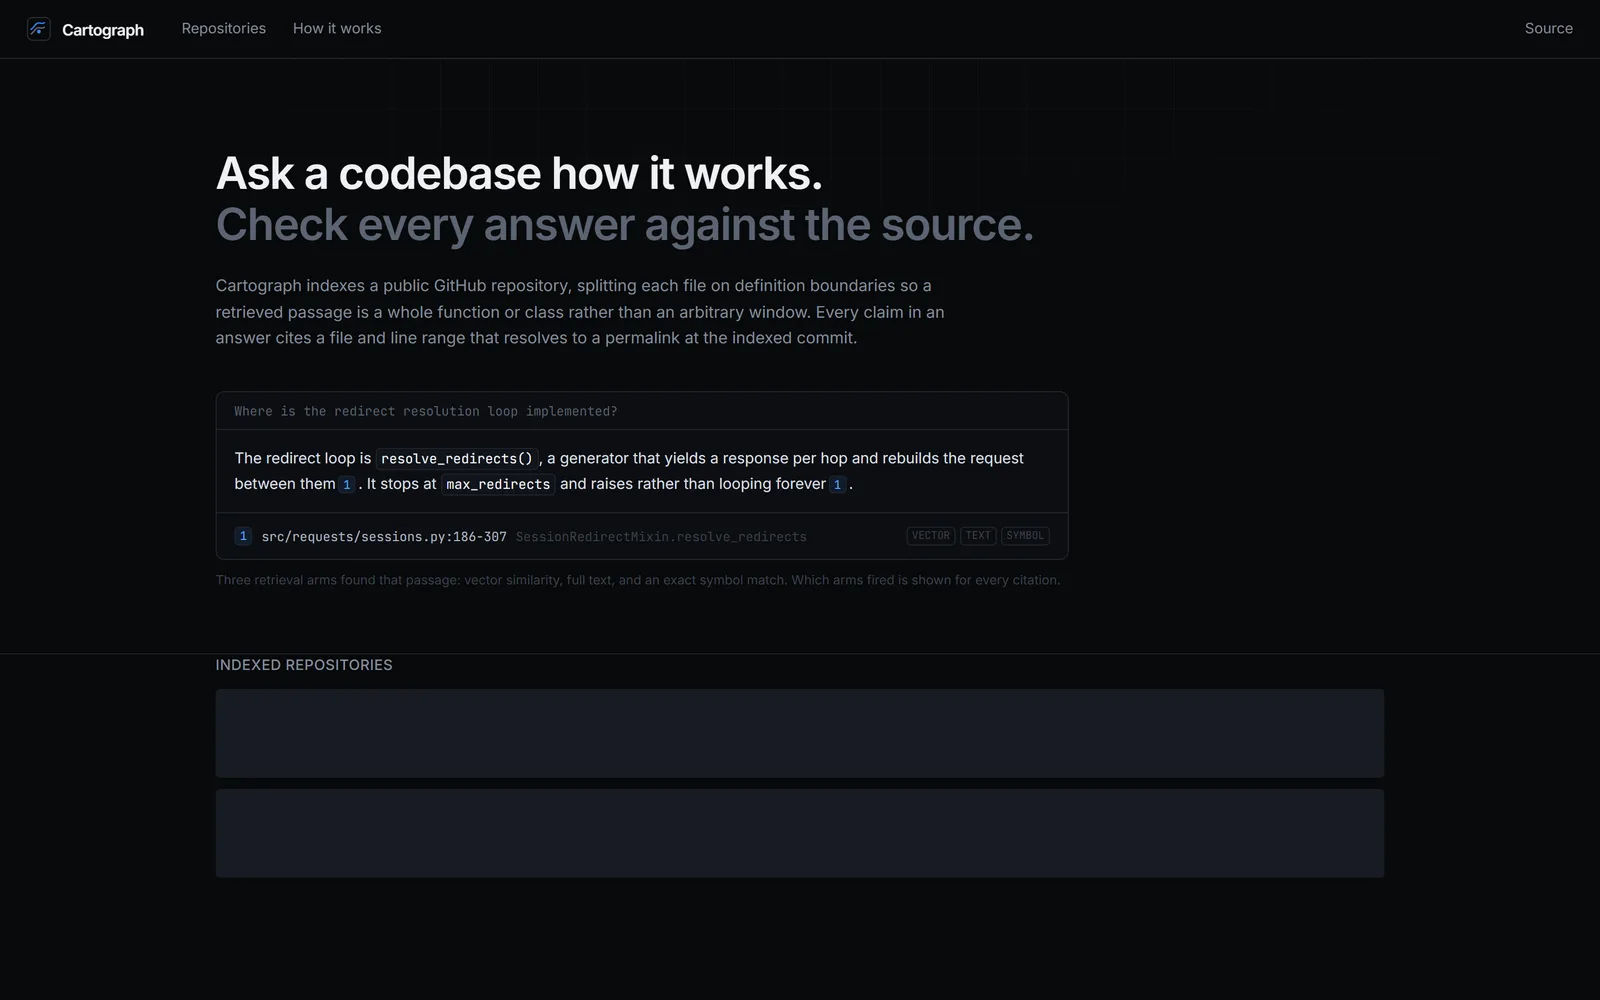
Built by this practice
How we engage
We start with your problem and constraints — what success looks like, and what it will take to get there.
A clear scope, milestones, and a realistic timeline, so you know what you're getting and when.
Iterative delivery with working software at each step — containerized and shipped, not left in a notebook.
Once it's live, we monitor, maintain, and improve it under real-world use.
Let's talk
Tell us what you're building. We'll help you scope it, build it, and ship it.